
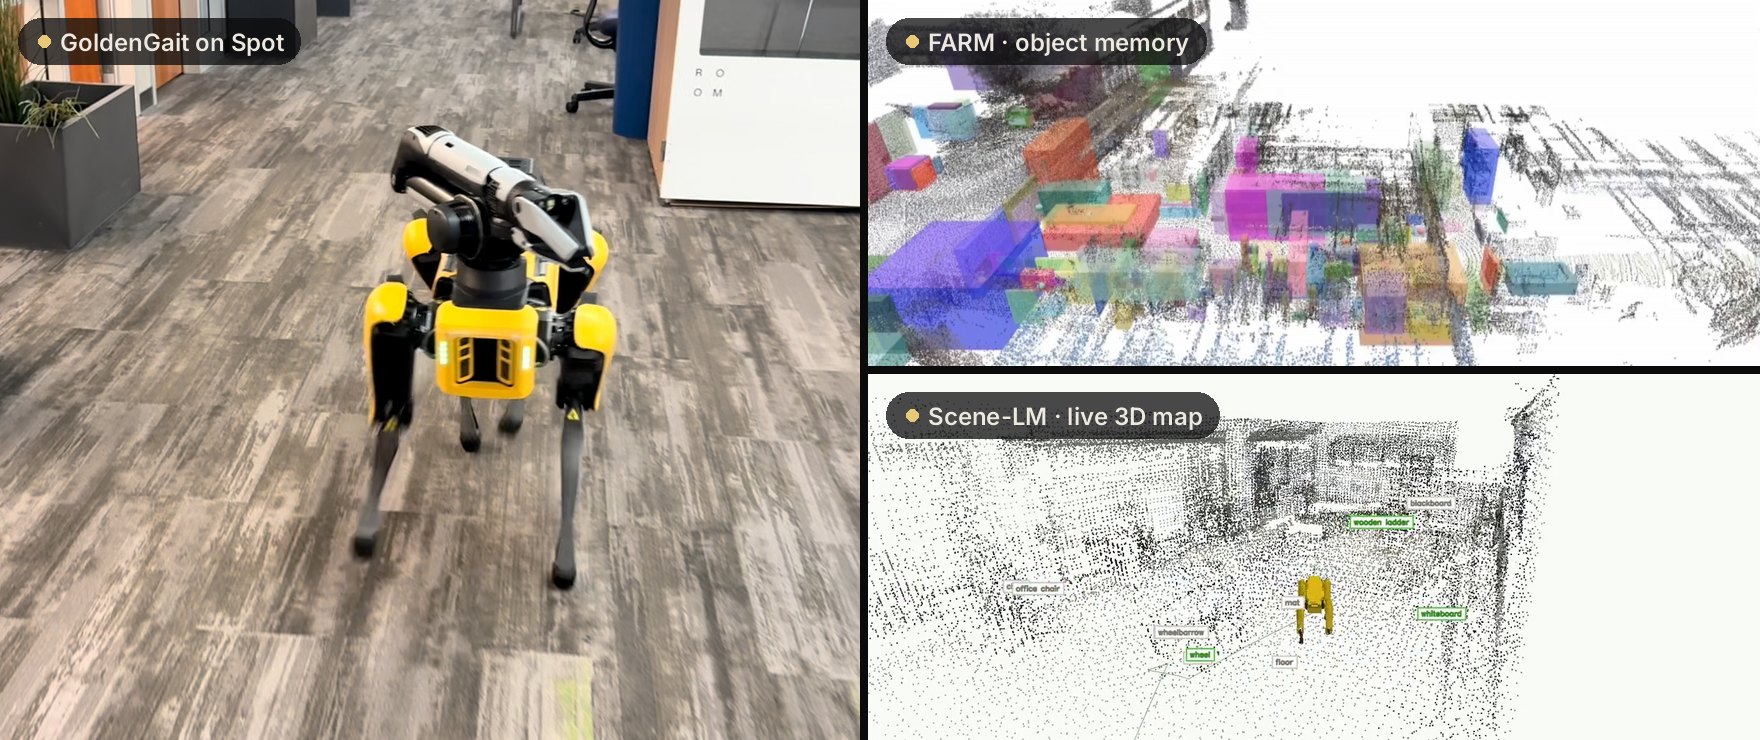
A vision-language agent drives a Boston Dynamics Spot to perceive, reason, and act on its own.
2nd place in Phase 1 of the DARPA Tiamat Program.
Building and deploying a full autonomy stack surfaces insights that a competition score never shows. We turn them into open research, code, and datasets.
| Project | Code | Links |
|---|---|---|
| FARM — Find Anything using Relational Spatial Memory | FARM-Project | Paper · Project page · Dataset |
| Scene-LM — A Scene Language Model for Open-Vocabulary Scene Mapping | Coming soon | Paper · Project page |
| GLST — Global-Local Spatio-Temporal Memory Decomposition Framework for Online Chained-Goal Navigation · Accepted, CoRL 2026 | Coming soon | Paper |
| GGraph — A GPU-Accelerated Library for Graph-Based Robot Deployment and Learning | Coming soon | |
| BT-Agent — Deploying Onboard Robot Agents with Behavior Trees and Multi-Fidelity Evaluation | bt-agent | Paper · Project page |
One memory, from a 74 m² room to a 15,000 m² construction site |
“Find the cardboard package under a white table.” · real robot, 10× |
Scene-LM running on Spot, outdoors |
One vision-language model builds the scene map |
Five targets, one run · real robot, onboard Jetson Thor |
Office navigation · real robot |
Forks with our own changes, kept public because our code depends on them:
yoloe— YOLOE open-vocabulary detector; used by FARM.autonomy_stack_go2— CMU's legged-robot autonomy stack, with our local-planner changes.odin_ros_driver— ROS driver for the Manifold Odin sensor.
UC Berkeley · Stanford University