

Build, inspect, and control your Python application’s dependency graph.


Browse Examples · Full Table of Contents · Roadmap
Beginner → Intermediate → Advanced → Expert
If you like the work we're doing, please give us a star on GitHub.
pip install melderOne dependency: pip. Nothing else comes with it. Requires Python 3.14+.
Releases are published to PyPI from this repository's release workflow, which signs every file it uploads
(PEP 740):
check a download with
pypi-attestations before you install it.
Working from a clone? Use the repository's uv.lock and
locked contributor setup.
On this page: First program · Basics · Managed pools · Agent rooms · Checkpoints · Documentation
Complete examples below run independently in a fresh Python process. Blocks marked Excerpt assume the classes or setup named in their prerequisites; do not paste separate examples into one long-running interpreter. Use a free-threaded Python 3.14+ build for the concurrency examples.
Beginner. A complete first program, including cleanup.
Prerequisites: install Melder, save this as hello.py, then run python hello.py.
import melder as md


class Greeter:
    """A plain class — no base class, no metaclass, no decorator."""

    def greet(self) -> str:
        return "hello from a melded instance"


book = md.Spellbook()
book.bind(spell=Greeter, existence="unique")

with book.conjure() as conduit:
    greeter: Greeter = conduit.meld("Greeter")
    print(greeter.greet())
    assert conduit.meld("Greeter") is greeter   # `unique` → same instance
# Leaving the block cleans the root conduit and its owned Spellbook.
Expected output: hello from a melded instance. The assertion checks reuse;
the block exit ends the scope. Your classes stay plain Python. Everything lives
on md.* — a deep import path is not needed for this workflow.
Pass the Python class or callable to bind; resolve it by its quoted registered
name with meld("Greeter"). The tutorials use this name-based lookup throughout.
Keep opaque machine identities explicit with meld(spell_id=...).
Melder™ wires your application together — services, config, connections, handlers — and hands you instances when you ask for them. That part will feel familiar if you've used a DI container.
The difference is what happens next. Dependency injection frameworks build your object graph and then forget it. Melder keeps it — as a live, inspectable, permissioned structure you can query, snapshot, restore, and change while the process is running.
For the one-picture distinction, open DI container versus Melder. For the system-level view, start with Architecture and design.
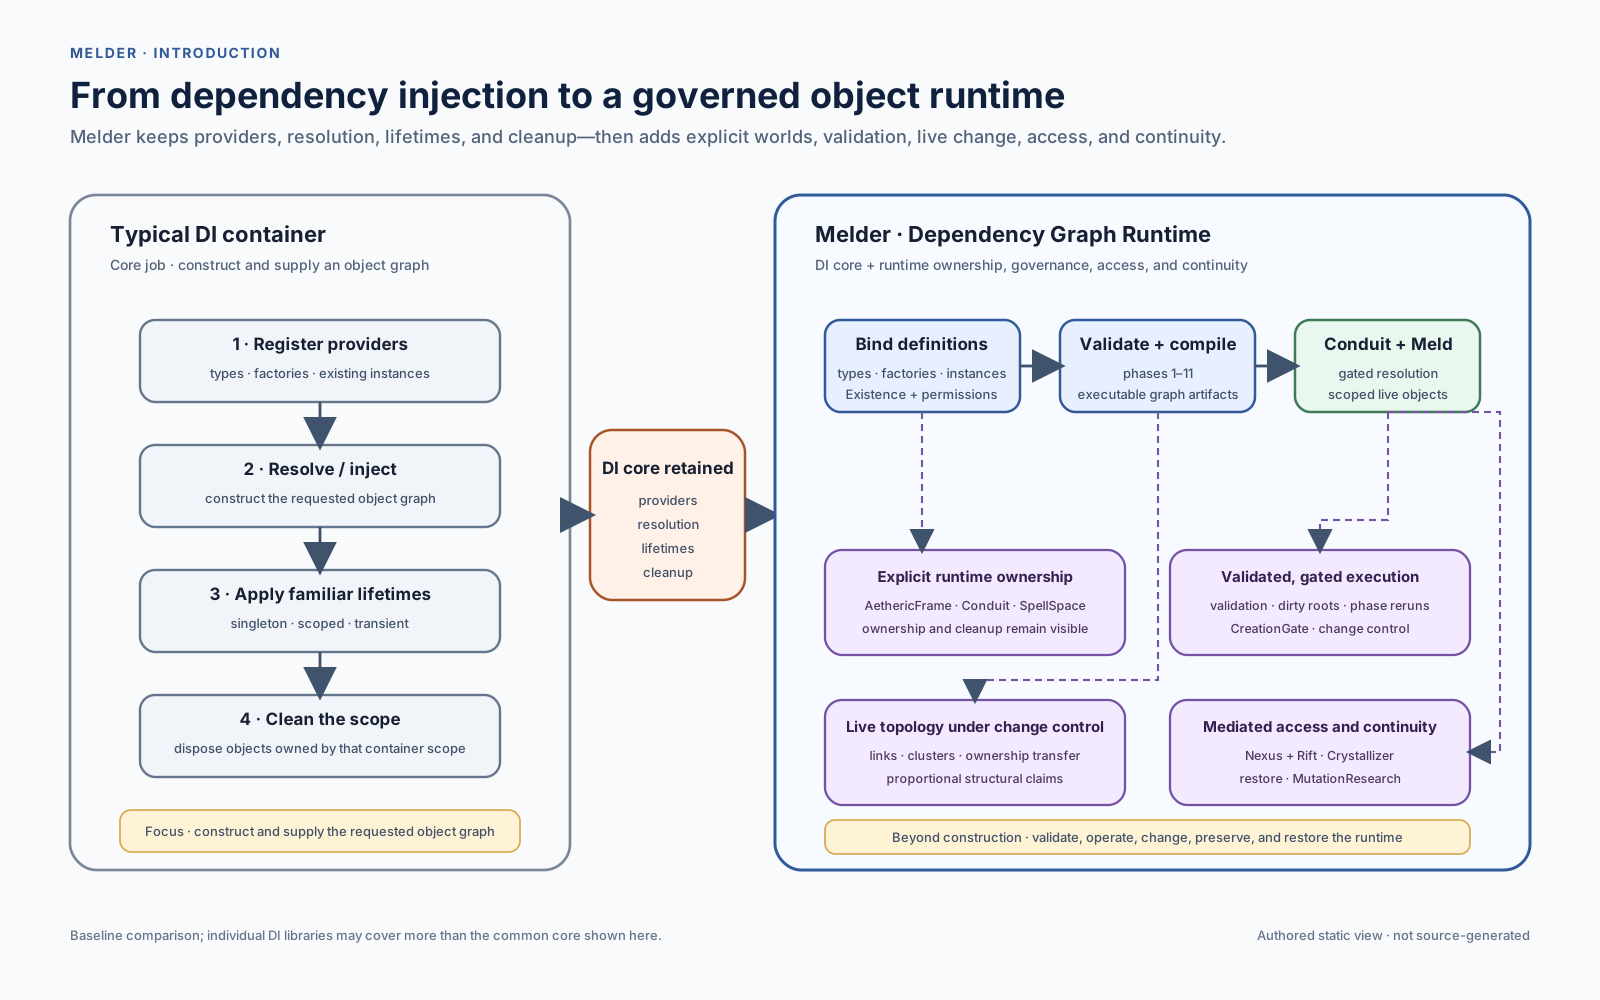
Three verbs. That's the entire mental model.
bind  →  register what exists          (classes, functions, instances)
conjure  →  compile + validate the graph   (once — check cycles and ambiguity)
meld  →  resolve instances             (as often as you like)
conjure() checks the registered graph, including cycles and ambiguous providers.
A typed parameter with no registered provider can remain a caller-supplied input:
the constructing meld() must supply it through override, or it raises
UnresolvedInputError. Dynamic changes can also require validation at a later meld.
Melder scales down to a script and up to a distributed backend. Find yourself here:
🟢 You're writing an app and tired of passing objects around Four lines gets you working DI with real lifetimes and automatic teardown. No config files, no YAML, no decorators, no base classes, and nothing new to install. If you've been threading a database handle through five function signatures, this is the fix.
🟢 You want your wiring checked before you ship it
conjure() compiles and validates the registered graph up front. Cycles and
ambiguous providers surface at startup with a specific error. Inputs deliberately
left for the caller are checked when a meld needs to construct their consumer.
🟡 You're building a web service and want honest request scoping Per-request scopes that actually end, per-connection lifetimes, and cleanup that fires deterministically instead of whenever the GC feels like it. Works with any framework — Melder doesn't own your entry point.
🟡 Your app outgrew a single container
One registry holding everything eventually becomes its own coupling problem —
every subsystem can see every other, and one conjure() has to know the whole
world before it starts. Instead, give each subsystem its own book and
conduit: it owns its registry, exposes only what its permissions allow, and
configures and tears down independently. Link them at runtime and pull specific
spells across the boundary — SpellContract even lets a consumer be built
before its provider exists, which a single shared container can't do.
🟠 You're running multi-tenant, plugin, or sandboxed workloads Aetheric frames are hard isolation walls inside one interpreter — separate registries, separate control planes, separate singletons. One process, many worlds, no leakage between them.
🟠 You write tests and want real isolation A fresh frame per test is a fresh world. No global container to reset, no state bleeding between cases, no ordering dependencies.
🚀 You're doing genuinely concurrent work on 3.14+ Lock-disciplined throughout with a documented one-way lock order, built for free-threading rather than ported to it. Resolution never enters the transaction plane, so concurrent reads don't contend.
🔵 You're building agent infrastructure Hand an AI a permission-bounded room over a live system: it can read the graph, work on real objects, execute validated code, preview a change's blast radius, and hot-swap an implementation — with every structural change transacted and reversible. See Part II.
🔵 You're building a framework or platform on top The runtime is introspectable by design — the graph is a real structure you can query, snapshot, restore, and extend. Melder carries its own architecture docs inside the package so tooling can read the system without importing it.
✨ And whatever you build, the doors are already there This is the part worth understanding before you start. You do not have to decide today whether your project will ever involve AI. Build a plain application with plain classes — and the moment you want an agent to read your architecture, operate on live objects under a permission set, checkpoint a world, or propose a change and be shown its blast radius, those surfaces are already in the runtime you're using.
No migration. No second framework. No rewrite. Nothing to bolt on. Anything you build with Melder can be opened up to agents whenever you're ready — because the doors were built in from the beginning, sitting closed until you turn the handle.
Straight answer, so you don't waste an afternoon:
- You need Python 3.13 or older. Melder requires 3.14+. That's not negotiable — the whole concurrency model assumes free-threading.
- You want autowiring by magic. Melder is explicit: you bind what exists. There's no classpath scanning that guesses your intent.
- You have three objects and a
main(). Just construct them. A DI runtime earns its keep when wiring becomes a real problem, not before.
Worth saying plainly: parts of Melder are designed for machines, not humans.
The AR rooms, the codegen surface, the research and impact views — those are built for an agent that can hold a whole object graph in working memory, issue hundreds of structured queries, and act on JSON-shaped answers. A human can drive them, and the API won't stop you, but you'd be hand-operating machinery built for something with different ergonomics than yours.
That's deliberate, and it's why "AI-native" is a claim rather than a label. These surfaces weren't retrofitted for agents after the fact — an agent is the intended operator.
None of it is on your critical path. Everything in Part I is written for humans first and stays complete on its own. If you never open a Rift or record a checkpoint, Melder is simply a fast, strict DI runtime and nothing is missing.
Melder is beginner-first by design. Four lines gets you a working graph, and
those four lines teach the whole runtime. Nothing in the advanced surface leaks into the simple
path — no mandatory configuration, no ceremony you must understand before your
first meld().
But the ceiling is very high. The same runtime that resolves your little service graph will checkpoint an entire distributed backend, hand an AI agent a permission-bounded room over live objects, and track every structural change under governance. You grow into it; it never asks you to grow into it first.
Melder holds very competitive speed against the fastest containers in
Python — it keeps up with dependency-injector and dishka, the two names
usually at the top of that list. And it does that while carrying a full graph
runtime: validation, permissions, lifecycle tracking, and introspection that
those containers don't attempt.
For any real application, DI resolution was never your bottleneck — I/O is. What you get for that parity is a system you can actually see.
The current AI tooling stack lives at the orchestration layer: chains, graphs of steps, prompt routing, tool registries. Those frameworks decide what an agent should do next, and they're good at it.
None of them answer the layer below. When an agent calls a tool, what is it actually touching? Usually a loose function with no identity, no lifetime, no ownership, no memory of having been called, and no way to undo what it did.
Melder is that missing layer — the low-level runtime an agent operates inside rather than a bag of callables it operates through:
| Orchestration layer | Melder (runtime layer) |
|---|---|
| Picks the next step | Owns the objects the step runs against |
| Tools are functions | Objects have identity, lifetime, and an owner |
| State lives in a scratchpad | State lives in scoped, permissioned instances |
| Changes are untracked | Every structural change is recorded and reversible |
| Access is all-or-nothing | Access is a compiled permission set per room |
The two compose cleanly. Let your orchestrator decide the plan — let Melder be the world the plan executes in, where the graph is inspectable, authority is bounded, and every change is accounted for.
Here's the part that has no equivalent elsewhere.
Most systems treat "the code changed" as something that happens to them — between deploys, invisibly, with a restart to absorb it. Melder treats structural change as an operation the runtime performs and records.
Versions of bound units live in lanes with forward-only history and content-addressed identity — a unit's content hash is its identity, so the same thing re-entering is recognized as a rediscovery rather than a duplicate. Before anything changes, you can ask:
- What's the blast radius? — everything transitively affected
- What drifted? — how the running world diverges from the sealed one
- What would happen? — a read-only preview of a candidate change: the diff, the radius, the verdict. Nothing executes, binds, or records.
An agent can propose a structural change, be shown exactly what it would break, and be refused — before a single object is constructed.
That's the difference between an AI that can call your system and an AI that can safely evolve it.
The planned path from API stabilization to a supported runtime and the Mojo migration.
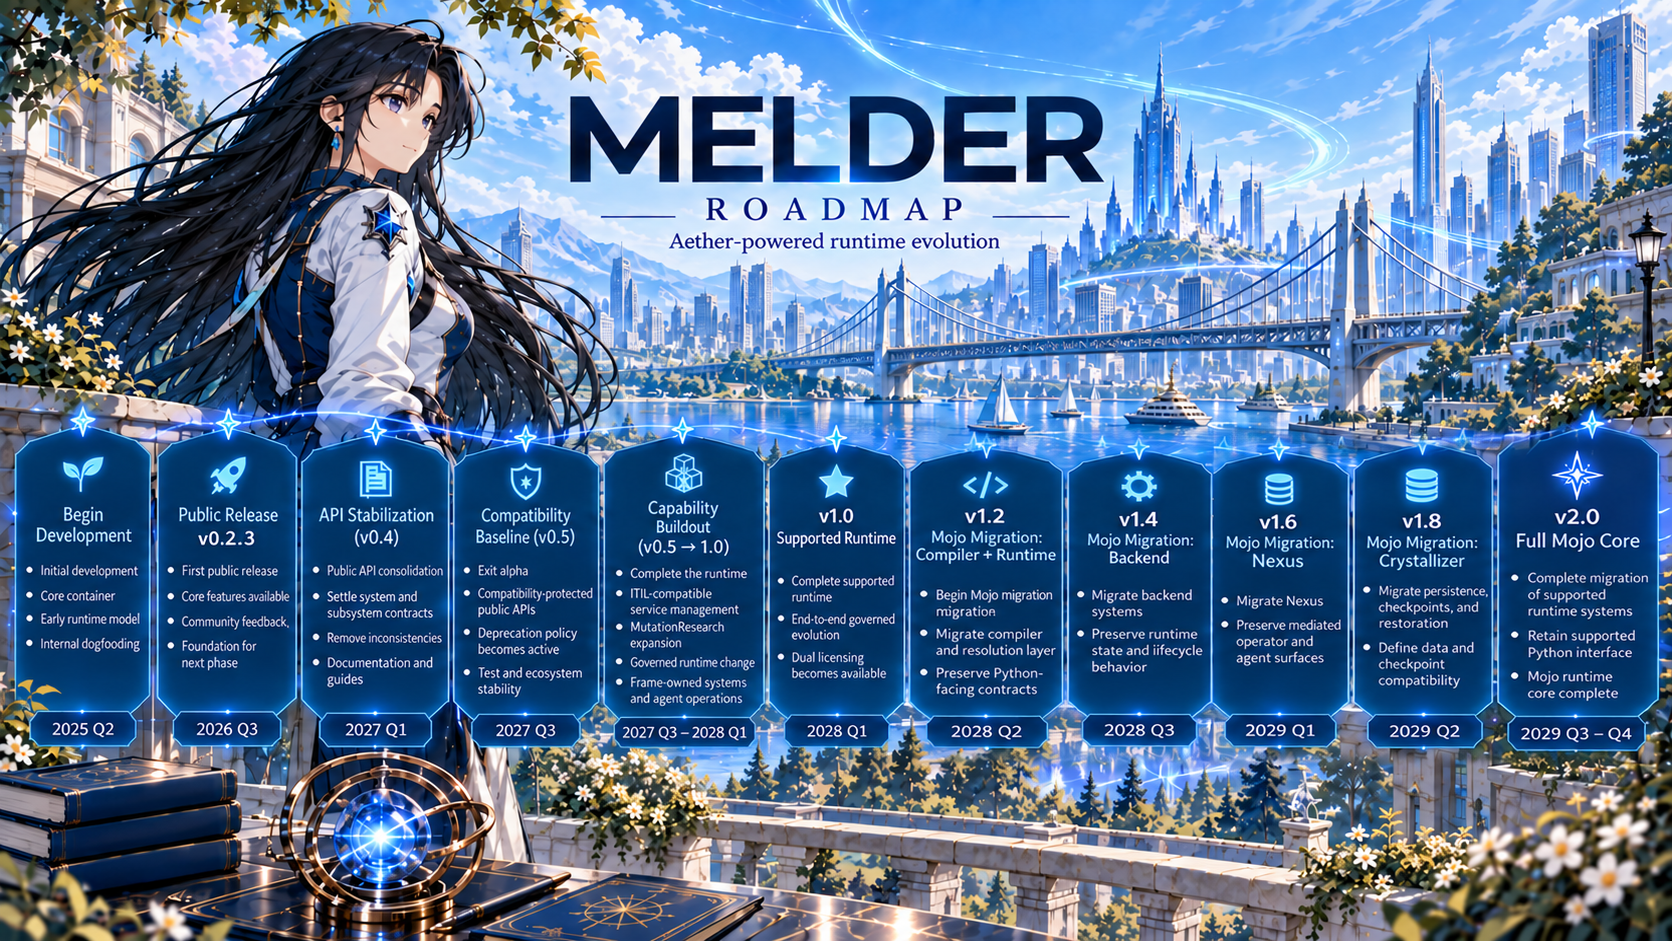
Read the detailed roadmap · Open the image at full size
Every section below is tagged with the level it belongs to. Read in order and stop wherever you have what you need — nothing later is required to use anything earlier.
| Level | What it means | Who it's for | Runnable examples | |
|---|---|---|---|---|
| 🟢 | Beginner | The core runtime. Bind, resolve, categorize, scope, clean up. | Everyone. Start here. | 01_beginner/ |
| 🟡 | Intermediate | Pooled resources, module registration, dynamic linking, late binding across subsystems. | When objects need reuse or subsystems need to connect. | 02_intermediate/ |
| 🟠 | Advanced | Frame isolation, read-only introspection rooms, clusters, deep overrides. | Multi-tenant or multi-world systems. | 03_advanced/ |
| 🔵 | Expert | Agent rooms, transactions, checkpoints, governed mutation. Mostly machine-facing. | Building on Melder, or handing it to an AI. | 04_expert/ |
This README is the tour. For system shape and design decisions, open
Architecture and design;
for the visual path, start with the
engineering drawings.
The folders above contain runnable scripts, verified together by the
pytest_examples/ harness.
Pick a route:
- Evaluating Melder: read What Melder is, then scan the engineering drawings.
- Building an application: try Hello, Melder, continue into
Part I, then work through
the
01_beginner/examples. - Building runtime or agent infrastructure: enter Part II,
then continue into the
04_expert/examples.
If you just want dependency injection, the 🟢 sections are the entire product. You can stop at the end of them and never open Part II. Everything past that point is optional capability that stays dormant until you turn it on.
Written for humans. Complete on its own.
🟢 Beginner → 🟡 Intermediate → 🟠 Advanced
Beginner. Three verbs, one order.
Excerpt. Config and Server are your application classes. Start with a
fresh book, register both, and conjure once; the final line returns a Server.
book = md.Spellbook()

# 1. bind everything
book.bind(spell=Config, existence="unique")
book.bind(spell=Server, existence="many")

# 2. conjure ONCE  ← compiles + validates the entire graph
conduit = book.conjure()

# 3. meld everywhere
server = conduit.meld("Server")
conjure() prepares the registered graph. Requirements extraction, graph
construction, cycle detection, and runtime compilation run there. Cycles and
ambiguous providers refuse startup. A typed parameter with no provider can be
supplied at meld(override={...}); omitting it when construction needs it raises
UnresolvedInputError. Ordinary Python parameter defaults remain defaults.
One book, one conjure. A Spellbook produces exactly one conduit, ever. More scopes?
create_lesser_conduit(). Another root? Another book.
Beginner. The one rule behind all resolution.
One rule governs all resolution:
Every spell lives at exactly one address:
(frame_key, binding_key)—frame_keyis thespellframeif given, else the spell's name;binding_keyis thebinding_nameif given, else the default slot.
Excerpt. Define both store classes and bind them before conjuring the conduit.
The lookup returns the PostgresStore registered as primary; the other binding
does not change which store that address selects.
book.bind(spell=PostgresStore, existence="unique", binding_name="primary")
book.bind(spell=SqliteStore,   existence="unique", binding_name="local")

primary = conduit.meld("PostgresStore", binding_name="primary")Beginner. The organizing half of every address.
A spellframe is the category half of the Address Law. It is a plain
string when you just want grouping, or a Protocol when you want a contract.
Nothing else is a spellframe: a concrete class is refused at bind() with a
TypeError that names the two forms (pass spellframe="Name" to group under
its name, or declare the shape as a typing.Protocol).
# strings — organize by role
book.bind(spell=UsersRepo, existence="unique",
          spellframe="storage", binding_name="users")
book.bind(spell=UsersApi,  existence="unique",
          spellframe="web",     binding_name="users")

repo = conduit.meld(spellframe="storage", binding_name="users")
api  = conduit.meld(spellframe="web",     binding_name="users")
This is an excerpt: define UsersRepo and UsersApi, bind them before
conjure, then resolve each full address. The result is a repository and an API
object in separate categories, even though both bindings are named users.
Same binding_name, two categories, two distinct addresses — names never
collide across spellframes. A string frame is only a label: it groups, it is
addressable, and it never makes its members providers of anything. A Protocol
frame is a label and a contract: bind() checks the spell against the
Protocol's own public members, records the Protocol on the binding, and a
parameter annotated with that Protocol resolves exactly its recorded
implementers — which is what collection DI gathers:
book.bind(spell=EmailHandler, existence="unique",
spellframe=Handler, binding_name="email")Beginner → Intermediate. Annotations, explicit targets, collections.
Annotate a constructor parameter. Melder builds the graph.
What an annotation selects depends on what it is. A class selects the spells of that type — a class
bound bare, or an existing object of that class — and nothing else: a category that happens to share the
class's name does not turn its members into providers. A Protocol selects the spells bound under it as
their contract. A TYPE_CHECKING-only import, which leaves a string at runtime, resolves by name to a
type or a contract, never to a string category. list[...] gathers the group the annotation's kind names:
every spell of the class, every implementer of the Protocol, or — for a string — every member of the
category or type of that name.
import melder as md


class Database:
    """A small stand-in for a database; this example performs no I/O."""

    def query(self) -> str:
        return "42 rows"


class ReportService:
    def __init__(self, database: Database) -> None:   # ← injected
        self.database = database

    def run(self) -> str:
        return "report over " + self.database.query()


book = md.Spellbook()
book.bind(spell=Database, existence="unique")
book.bind(spell=ReportService, existence="unique")

with book.conjure() as conduit:
    report: ReportService = conduit.meld("ReportService")
    assert isinstance(report.database, Database)
    print(report.run())
This complete example prints report over 42 rows: melding the consumer first
constructs its registered dependency and injects it into the constructor.
When an annotation isn't specific enough — two implementations of one shape, or
a named binding — declare the target with SpellMap as the parameter default:
Excerpt. PrimaryStore must already be defined and registered in this book.
class Consumer:
    def __init__(self, store=md.SpellMap(PrimaryStore)) -> None:
        self.store = store
SpellMap takes the full address: a concrete spell, a spellframe, a
binding_name, or a combination. It obeys an exactly-one law — a target
that matches zero spells or several fails at conjure(), not at runtime.
When a single Protocol-annotated parameter has several registered implementations,
conjure() refuses with an AMBIGUOUS_PROVIDER
report that lists every candidate's address and the fix — a SpellMap
default, a meld override, or one provider — never a guess.
Registering the same class twice is instead refused as a duplicate spell identity
at registration; another binding name does not make it a different spell.
Ask for a list and get every implementation — the plugin pattern in one annotation:
Excerpt. Define the Handler Protocol and both implementing classes first;
bind the dispatcher as well before conjuring. The complete
collection-injection lesson
includes those definitions and prints ['email', 'sms'] from its injected handlers.
class Dispatcher:
    def __init__(self, handlers: list[Handler]) -> None:   # ← all of them
        self.handlers = handlers

book.bind(spell=EmailHandler, existence="unique",
          spellframe=Handler, binding_name="email")
book.bind(spell=SmsHandler, existence="unique",
          spellframe=Handler, binding_name="sms")
book.bind(spell=Dispatcher, existence="unique")Beginner. Pick how long things live.
| Existence | One instance per | Use it for | |
|---|---|---|---|
| 🟢 | unique |
Process (frame) | Config, pools, caches |
| 🟢 | unique_per_conduit |
Scope | Request / session state |
| 🟢 | many |
Nothing — new every meld | Stateless workers, DTOs |
| 🟡 | unique_per_conduit_lineage |
A scope and its children | Shared context down a tree |
| 🟡 | unique_per_spell_space |
A request-local space | Ephemeral request scoping |
| 🟡 | managed_spell_quantity |
Nothing — leased from a pool the root keeps | Costly objects reused across holders |
| 🟠 | unique_per_conduit_cluster |
A named group of scopes | Cross-scope coordination |
The first three are the beginner set — they cover most systems and need nothing but a static conjure. The rest arrive with the need that gives them meaning: lineage and spell spaces once you have nested scopes, managed pools once an object costs more to build than to lend, clusters once conduits link into groups.
For the intermediate leasing and release example, see Managed Spell Quantities.
Callables are always
unique. Want a fresh object every time? Bind a class asmany.
Beginner. Cleanup without ceremony.
Excerpt. Define the connection and worker classes with their cleanup methods
first. Registration declares how to dispose them; meld() creates the instances
whose matched methods run when the conduit ends.
Declare your teardown vocabulary — the method names that mean "clean yourself up" in this system — and Melder calls them on the way down. No base class, no protocol, no context-manager ceremony:
book = md.Spellbook()

book.bind(
    spell=PooledConnection,
    existence="unique",
    disposal_method_names=["close", "shutdown"],   # this binding's ordered methods
)
book.bind(
    spell=BackgroundWorker,
    existence="unique",
    disposal_method_names=["shutdown"],
)

conduit = book.conjure()
connection = conduit.meld("PooledConnection")
worker = conduit.meld("BackgroundWorker")
conduit.cleanup()     # calls each creation's matched methods in their declared order
Each bind's list belongs to that spell, not every later bind. Melder resolves matching class methods once at bind time and preserves their order:
- If the connection implements both names,
close()runs beforeshutdown(). - The worker uses its own
shutdown()declaration. - Missing names are omitted; duplicate names execute once.
For book-wide methods, use SpellbookConfiguration. Its matching methods form
one ordered block: last by default, or first with
with_enforce_priority_disposal_methods(True). Shared names belong to the book's
block in either mode; spell-only names retain their own order. See the
configuration guide
for both arrangements.
Within each store, objects are disposed newest first, so a dependency outlives the
objects built on it. A failing method does not stop the others: every declared
method of every object runs, each failure is chained from what the method raised,
and they are raised together as one ExceptionGroup once the scope has ended.
A managed_spell_quantity return normally resets the object for reuse. Its
disposal methods run when the pool destroys it — an elastic trim, a reset
that raises, or the root's teardown.
Beginner. Child scopes, no configuration.
import melder as md


class Config:
    """Shared configuration for this example."""


class Session:
    """State scoped to one conduit."""


book = md.Spellbook()
book.bind(spell=Config, existence="unique")
book.bind(spell=Session, existence="unique_per_conduit")

with book.conjure() as root:
    with root.enter_lesser_conduit() as child:
        assert root.meld("Config") is child.meld("Config")       # shared
        assert root.meld("Session") is not child.meld("Session") # per-scope
Expected outcome: both assertions pass, with no printed output. The child scope ends first, then the root; a child does not create another book or another root.
Intermediate. Lease, reset, and reuse objects across requests.
Bind a class with existence="managed_spell_quantity" when its objects cost
more to build than to lend. Each meld or constructor injection leases an
idle object from the owning root's pool, or builds one when the mode allows.
The holder returns it with md.ReleaseManagedSpell().release(obj), or uses
managed_spell_meld(...) to return it when a with block ends, even if the
block raises.
This complete example combines the intermediate lessons on reset methods, leases, and request-scoped injection:
- Bind the buffer pool and a job that receives a buffer through injection.
- Meld the job inside a request scope and write report data into its buffer.
- End the request:
finish()releases the buffer andreset()clears it. - Lease that buffer again and check that it is the same object, now empty.
- End the root: the idle buffer's
close()method runs.
import melder as md


class ReportBuffer:
    """Reusable report state; reset on release, closed only when disposed."""

    def __init__(self) -> None:
        """Start empty and open; closed is a diagnostic flag for this example."""
        self.lines: list[str] = []
        self.closed: bool = False

    def reset(self) -> None:
        """Remove the previous request's data before the next lease."""
        self.lines.clear()

    def close(self) -> None:
        """Dispose the buffer; retain closed so the example can check teardown."""
        self.lines.clear()
        self.closed = True


class ReportJob:
    """Hold one injected buffer until the request scope disposes this job."""

    def __init__(self, buffer: ReportBuffer) -> None:
        """Borrow one pooled buffer; this job must release it exactly once."""
        self.buffer: ReportBuffer = buffer
        self.finished: bool = False

    def finish(self) -> None:
        """Give the buffer back once; the job must stop using it afterwards."""
        if self.finished:
            return
        self.finished = True
        md.ReleaseManagedSpell().release(self.buffer)


def main() -> None:
    """Return a request's buffer, reuse it reset, then dispose the idle buffer."""
    book = md.Spellbook()
    try:
        book.bind(
            spell=ReportBuffer,
            existence="managed_spell_quantity",
            managed_spell_mode="limited_quantity",
            managed_spell_limit=1,                  # one alive: idle or leased
            managed_spell_reset_methods=["reset"],  # every return, before reuse
            disposal_method_names=["close"],        # only when the pool destroys one
        )
        book.bind(spell=ReportJob, existence="many", disposal_method_names=["finish"])

        with book.conjure() as root:
            with root.enter_lesser_conduit() as request:
                job: ReportJob = request.meld("ReportJob")
                job.buffer.lines.append("Sales: 120")
                previous = job.buffer  # retain identity only to demonstrate reuse
            # Request exit called job.finish(): the buffer is reset and pooled.

            with root.managed_spell_meld("ReportBuffer") as reused:
                assert reused is previous
                assert reused.lines == [] and not reused.closed
                reused.lines.append("Sales: 240")
            # The lease block returns and resets the buffer again.

        assert previous.closed  # root exit disposed the idle buffer
    finally:
        book.cleanup()


if __name__ == "__main__":
    main()
Expected outcome: the assertions pass and nothing is printed. The retained
previous reference is only a diagnostic for identity and teardown; application
code must stop using a buffer after releasing its lease.
Choose the mode at bind:
managed_spell_mode |
What managed_spell_limit caps |
When nothing is idle |
|---|---|---|
elastic (default) |
Idle objects kept, 256 by default | Builds another; trims extras on return as demand falls |
limited_quantity |
All objects alive, idle plus leased; required | Builds below the limit, otherwise raises md.ManagedSpellExhaustedError |
queue |
All objects alive, idle plus leased; required | Builds below the limit, otherwise waits up to the required managed_spell_timeout_seconds, then raises md.ManagedSpellExhaustedError |
Queue and limited quantity share the same allocation and reuse rules. Both
start empty, build on demand below the limit, and reuse returned idle objects.
They differ when nothing is idle and every place is occupied: limited_quantity
refuses that attempt without waiting for capacity; queue waits on the calling
thread for an object or a free place. It does not start a background worker.
For queue, managed_spell_timeout_seconds is required and must be finite and
greater than zero. It is rejected for limited_quantity and elastic. The
deadline is taken once; wakeups do not restart it. It bounds the capacity wait,
not the time a constructor or the rest of the meld takes.
To choose queue instead of the registration above, use this alternative before
conjure in a fresh run; do not bind ReportBuffer twice:
book.bind(
    spell=ReportBuffer,
    existence="managed_spell_quantity",
    managed_spell_mode="queue",
    managed_spell_limit=1,
    managed_spell_timeout_seconds=2.0,
    managed_spell_reset_methods=["reset"],
    disposal_method_names=["close"],
)
With capacity 1, suppose caller A holds the only buffer and caller B asks for another while A can still release it:
| Event | limited_quantity |
queue with a 2-second wait |
|---|---|---|
| B asks while A holds the buffer | B gets ManagedSpellExhaustedError |
B waits; no second buffer is constructed |
| A releases before the deadline | B must explicitly retry | B can receive the same buffer, after its reset |
| A never releases | B has already failed | B gets ManagedSpellExhaustedError when its deadline expires |
A thread holding the only buffer cannot release it later in the same sequential flow while its second meld is waiting: that queue attempt times out. Waiting is useful when another holder can make progress. Queue does not promise FIFO caller ordering, and an exhausted attempt never takes an existing holder's object away.
Reset methods run in the declared order on every return. Disposal methods run when the pool destroys an object: an elastic trim, a reset that raises, or root teardown. Return each lease exactly once and stop using the object afterwards. Each injected parameter takes its own lease, so two live jobs hold two buffers.
End request scopes before the root. The root owns the pool and disposes its idle objects at teardown; an object still leased stays its holder's to dispose. A job that releases from its disposal method belongs in a lesser scope, as above: the root's own disposal methods run after its pools are gone.
Continue with the managed spell guide or run the intermediate examples: limited quantity, reset methods, leases, and injection and request scopes.
Intermediate. Register where the class lives.
Prefer to declare registration where the class lives? Tag it with
@md.scan_bind, then register the whole module in one call.
services.py — declare intent next to the code:
import melder as md


@md.scan_bind(existence="unique", permissions="create")
class MetricsHub:
    pass


@md.scan_bind(existence="many", permissions="create")
class JobTicket:
    pass
main.py — decide when it actually binds:
import melder as md
import services

book = md.Spellbook()
bound = book.scan(services)        # ← binds every tagged class in the module
conduit = book.conjure()

hub = conduit.meld("MetricsHub")
The decorator stores intent only — nothing touches the runtime until
scan() runs. Importing services registers nothing: no hidden global
container filling up behind your back, no import-order puzzle to debug. You
still decide when binding happens, and where.
Mix freely: scan a module, then bind() a few more by hand.
scan_bind takes everything bind() takes for a target — spellframe,
binding_name, resolvable, disposal_method_names and your own metadata
keywords — and permissions is required. Only the decorated class or function
itself is registered: its subclasses and instances are not, unless they are
decorated too.
Intermediate. Everything above works without this. Turn it on when separate parts of your system need to share.
By default a world is static — bind, conjure, resolve. Turn on dynamic mode and conduits gain the ability to connect to each other at runtime.
Prerequisites for the excerpts below: use a fresh process; create
owner_book and borrower_book, define SharedDirectory, and capture its
spell_id from owner_book.bind(...) before conjuring. The complete
dynamic-linking lesson
includes all of that setup and prints the provider's found result.
The mode is decided once, by the first conjure, and then inherited:
# SETTLEMENT — the first conjure on a fresh world sets the mode, and it locks
owner = owner_book.conjure(dynamic=True, name="owner")

# INHERITANCE — later books just attach; a plain conjure() inherits the mode.
# You never repeat the flag.
borrower = borrower_book.conjure(name="borrower")
Now link them and share a spell across the boundary:
owner.link(borrower)                       # open a contract between the two

borrower.add_spell_to_contract(            # ← the BORROWER asks
    spell_id=spell_id,
    conduit=owner,                         # ← from the conduit that OWNS it
    permissions="create",
)

shared = borrower.meld("SharedDirectory")   # resolves the owner's spell
Expected outcome: the borrower resolves the registered provider after linking and pulling its spell into the contract. The link alone does not grant it.
Sharing is a pull, never a push. The conduit that wants the spell asks for it, and names the owner. An owner cannot force its objects into someone else's scope — so nothing arrives in your conduit that you didn't request.
Intermediate. Wire whole subsystems together without either side importing the other.
Excerpt. Define the ConfigContract Protocol, register its provider in
platform_book, and bind the consumer in services_book first. config_id and
service_id below are the IDs returned by those registrations. Run the complete
late-binding lesson
for the definitions and full sequence.
A SpellContract is a hole you leave on purpose. The class declares the
shape it needs; the provider arrives later, across a link:
class ReportService:
    def __init__(
        self,
        config: ConfigContract = md.SpellContract(
            spellframe=ConfigContract, binding_name="platform",
        ),
    ) -> None:
        self.config = config        # ← filled from another conduit entirely
Name your conduits after the resolution ideas your app already has — platform,
services, workflows — and the conduit names become your factory layer. No
abstract factories, no service locator, no imports between subsystems.
The order of operations is the law. Per dependency edge, in this exact order:
platform = platform_book.conjure(dynamic=True, name="platform")  # 1. provider
services = services_book.conjure(dynamic=True, name="services")  # 2. consumer
platform.link(services)                                          # 3. link — AFTER both exist
services.add_spell_to_contract(                                  # 4. consumer pulls
    spell_id=config_id, conduit=platform, permissions="create",
)
service = services.meld(spell_id=service_id)                    # 5. meld completes the binding
Expected outcome: service.config is the contracted provider object. The saved
lesson's equivalent store example prints region-ok; these excerpts do not print.
Assemble the chain edge by edge, in dependency order. services can then feed
workflows with the identical five steps one level up — the finished product of
one category becomes the dependency of the next.
Advanced. Hard isolation walls inside a single interpreter.
Everything so far has lived in one aetheric frame — the default world. A frame is the outermost boundary in Melder: it owns its own conduits, registries, control plane, and dynamic posture. Name a different one and you get a second world that shares nothing with the first:
tenant_a = md.Spellbook(aetheric_frame="tenant-a")
tenant_b = md.Spellbook(aetheric_frame="tenant-b")
Bind a distinct class in each world — a subclass per tenant is enough. A spell
ID is the SHA256 of the registered object's code (its methods, constructor,
class-level values and bases), with nothing from the bind call in it, and spell
IDs are unique across the process: the same class bound in another frame is the
same spell, and it is refused whatever binding_name or spellframe it gets.
A unique spell is a singleton per frame — not per process. Two classes,
two frames, two instances, one interpreter. To register one class in several
worlds instead, turn process_wide_unique_spell_ids off in the Aether
configuration before the first frame exists; spell IDs are then unique per frame.
That makes frames the natural seam for multi-tenancy, plugin isolation, and test isolation (a fresh frame per test is a fresh world). Conduits link within a frame; they do not link across one — the wall is real.
Don't confuse the two "frames":
spellframe=is an address key that categorizes spells inside a world.aetheric_frame=is the world itself.
Once you see it, the same idea repeats at three scales — each one a wider boundary than the last:
| Scale | Categorizes | Owner |
|---|---|---|
spellframe |
Spells within one world | The book that bound them |
| Conduit | Worlds of resolution, linked by contract | Each conduit owns its category |
aetheric_frame |
Entire isolated worlds | The frame itself |
Pick the narrowest one that expresses what you mean. Most systems need only the first; large ones grow into the second; the third is for genuine isolation.
Advanced. A safe window onto a running system — no agent required.
You don't need to be building AI to want a live view of your own runtime. A
static Nexus room is exactly that: a read-only projection over a running frame
that can inspect everything and change nothing.
That makes it a natural backing for the introspection surfaces you'd otherwise hand-roll:
- a health endpoint that reports what's genuinely live, not what you hope is
- an admin panel listing resolved services and their scopes
- a debug view of the real dependency graph in production
Because the room's authority is compiled and read-only, exposing it carries no
mutation risk — the worst a caller can do is look. The capability and
codegen rooms in Part II escalate from here.
Real surfaces this page doesn't walk through — all covered in the documentation:
| Surface | What it does | |
|---|---|---|
| 🟡 | Spell spaces | Request-local scopes backing unique_per_spell_space |
| 🟡 | Registration hooks | pre / activation / post callbacks on the bind lifecycle |
| 🟡 | SpellBinder |
A fluent chained alternative to bind(...) |
| 🟡 | Ownership transfer | Move a spell's stewardship between conduits at runtime, repointing borrowers and clusters |
| 🟠 | Conduit clusters | A named group of scopes sharing one instance, with an elected leader |
| 🟠 | Deep override paths | Inject a variant into the middle of a live graph at meld time — override={"transport>credentials": obj} — without rebinding anything |
Mostly written for agents. Optional, and off unless you turn it on. Everything above is a very good DI container. This is why Melder exists.
A note on the audience. The surfaces below assume an operator that reads structured output fast and issues many precise calls — an agent, in other words. They're documented here so you know the ceiling exists and can reason about what you're handing an agent. You are not expected to drive them by hand, and nothing in Part I depends on any of it.
Expert / agent-facing. The package carries its own architecture.
Melder ships its own architecture as queryable objects inside the wheel. An agent reads the system before touching it — no web, no scraping, no RAG:
import melder as md

md.__architecture__     # system architecture (C4)
md.__components__       # component catalog
md.__graph_network__    # object relationship graph
md.__graph_details__    # detailed wiring

help(md)                # the workflow map
Most frameworks make an agent guess from source. Melder hands it the map.
Expert / agent-facing. Bounded authority over a live frame.
Nexus is the mediated access layer into the live object world. You open a
Rift — a workspace over a running frame — and the room decides how much
authority the occupant has.
Excerpt. This assumes an activated nexus and an appropriate
rift_configuration. The complete codegen example below shows the activation,
room type, application frame and registration explicitly.
rift = nexus.create_rift(configuration=rift_configuration, rift_name="alpha")
conduit = rift.create_nexus_frame(frame_name="ops")   # rooted, live
Three room postures, escalating:
| Room | What the occupant can do |
|---|---|
static |
Read-only. Inspect live spells, never mutate topology. |
capability |
Discover conduits, traverse contracts, activate spells, mutate topology. |
codegen |
Everything above plus write and execute Python against live objects. |
static is covered back in Part I — it needs
no agent and works fine as a plain introspection endpoint. The two below are
where authority starts escalating.
This complete example needs a fresh process with Melder installed. It first
creates an observable dynamic application frame and binds a service, then
activates Nexus and explicitly chooses a codegen room. Nexus's default room
type is static, which does not expose execute_codegen.
The workstation keeps a callable target. A service instance is not callable
merely because it has methods, so bind service.run in the methods store. The
example invokes it once through the workstation and once through generated code.
import melder as md


class ReportService:
    """A service whose run method is exposed through the room's workstation."""

    def run(self) -> str:
        return "report ready"


def main() -> None:
    """Create a codegen room, call a bound method, then end its owned scopes."""
    frame_name = "readme-agent"
    configuration = md.SpellbookConfiguration(frame_name).with_defaults().finalize()
    book = md.Spellbook(aetheric_frame=frame_name, configuration=configuration)
    book.configure_aether_frame(
        system_state="dynamic", disposal=None, disposal_method_names=None,
        rift_enabled=True, ai_native=True,
    )
    book.bind(spell=ReportService, existence="unique", permissions="create")

    with book.conjure(name="agent-root") as root:
        nexus = md.Nexus()
        system_configuration = nexus.create_configuration()
        system_configuration.with_rift_creation_enabled(True)
        system_configuration.with_allowed_target_frame_names([frame_name])
        nexus.activate(system_configuration)
        rift_configuration = nexus.create_rift_configuration().with_space_type("codegen")
        rift = nexus.create_rift(configuration=rift_configuration, rift_name="alpha")
        try:
            rift.mark_active()
            rift.create_frame_link(frame_name)
            workstation = rift.space.workstation
            command = rift.space.command_system

            service: ReportService = root.meld("ReportService")
            workstation.bind_method("report", service.run, weak_ref=False)
            workstation.set_target("report", store="methods")
            print(workstation.call_target())

            outcome = command.execute_codegen("result = target()\n", frame_name=frame_name)
            assert outcome["accepted"] is True, outcome
            assert outcome["result"] == "report ready"
            print(outcome["result"])
        finally:
            rift.cleanup()


if __name__ == "__main__":
    main()
Expected output: report ready twice. The second call is validated before
execution; its public result payload reports accepted and the generated
result. The room can expose viewer, workstation, target, command and
codegen alongside its configured Python execution environment. Here target
is the selected bound method, not the service instance.
The agent inspects the running system, works on real objects, and writes code against them — without ever holding a reference to your process.
And the ACL is a dial, compiled per frame:
imports_enabled          = False        # no imports at all
allowed_import_module_roots = ("json",) # ...or exactly these
denied_builtin_names     = ("eval",)    # kill specific builtins
unsafe_reflection_allowed = False       # no type()/introspection escapes
dunder_access_allowed    = False        # no __class__ walks
recursive_codegen_allowed = False       # code that writes code
Every generated fragment is validated before it executes. import math in a
json-only room is rejected. type(command) in a reflection-denied room is
rejected. The agent gets a real seat at the runtime, bounded by a permission set
you wrote.
Expert. How concurrent structural change stays safe.
The obvious question about everything above: if an agent can rewire my topology while the system is running, what stops it corrupting the world?
Melder carries a full internal DevOps environment — a control plane that admits, serializes, and audits every structural change. It isn't a lock around the container. It's a transaction system with ACID semantics over the object graph.
Every structural mutation is a transaction in a named family:
bind · link · unlink · cluster_link · transfer_ownership
add_to_index · remove_from_index · notch
Each one declares the scopes it touches and the mode it needs, then a mediator admits it — or makes it wait.
Atomicity — Scope acquisition is all-or-nothing. A request takes every scope it needs or none of them, and owns exactly one root session. Failures compensate: a refused operation rolls back its claims, and a mid-operation refusal restores everything it had already moved, in original order.
Consistency — Changes propagate as invalidation, not corruption. Touching a lineage marks dependents dirty; the resolver refuses to execute a stale graph and recompiles it first. A built-in consistency audit walks every bidirectional map looking for asymmetry — any mismatch is evidence a write bypassed the plane.
Isolation — Claims are moded, not binary: x exclusive, s shared, ix
intent. Disjoint work admits in parallel; shared and intent claims coexist on the
same scope; exclusive excludes everything. Two subsystems binding into different
books never see each other. Two operations targeting the same conduit serialize.
Waiting is bounded, and a timeout names which scope blocked and who held it —
not a generic deadlock.
Durability — Committed structure is recorded to the persistence twin and survives into checkpoints (next section).
Two design choices worth calling out:
- Readers never enter the plane.
meld()doesn't take transaction locks — resolution stays fast and is protected by validity gating instead. You pay for coordination only when you change something. - Ownership is asymmetric on purpose. Sharing is a pull: the conduit requesting a spell must be the one that gets it, and an owner cannot push its objects into someone else's scope.
There's also a queryable operations catalog — live transaction activity, cluster fan-out, the blast radius of a proposed ownership transfer, a whole-frame operational rollup, and that registry consistency audit. It's caller-paid: nothing runs it for you, and it costs nothing until asked.
The DevOps plane isn't a side feature — it's the reason the rest of this README is safe to promise. Every capability above and below runs through it:
| Capability | What the plane guarantees |
|---|---|
| 🟡 Linking conduits | link / unlink are transactions. Two subsystems wiring themselves simultaneously serialize on the shared scopes and proceed in parallel everywhere else. |
| 🔵 Hot-swapping a live spell | notch is a transaction. The index repoint, the parking of the old version, and dependent invalidation land atomically — a meld never observes a half-swapped index. |
| 🔵 Agents mutating topology | Generated code has no privileged path. command.link_frame(...) from a codegen room enters the same plane, takes the same claims, and waits like anything else. |
| 🔵 Checkpoints | Only committed structure is recorded. A checkpoint can't capture a half-applied transfer, so a restored world is one that actually existed. |
| 🚀 Parallel everything | Moded claims mean disjoint work never contends. This is what makes concurrent structural change fast rather than merely survivable. |
Take the plane away and every one of those becomes a race condition. That's why it's here, and why an agent gets to touch a live system at all.
Expert. Persistence, cold boot, and pod restarts.
Crystallizer records a digital twin of your configured system — structure,
never live instances:
Prerequisites: activate recording before the application bindings you want to capture. With recording active, create finalized book configurations and a dynamic frame before binding. The complete checkpoint-and-restore lesson shows those application-building steps and verifies that restored objects start with fresh application state.
Excerpt — recording and saving: place the configured application-building
steps between activation and create_checkpoint. The assertions distinguish
the in-memory ledger from the durable local cache. This needs write and read
access to <melder package>/__melder_cache__/__crystallizer_cache__/; the cache
is under the Melder package, not the caller's working directory.
Local caching needs no external persistence manager or separate enable switch: activate the recorder, then explicitly flush. This demonstration starts a new named profile so it does not mix a new recording chain with cached history from another run. Keep the printed profile name for the cold-process bootstrap below.
from uuid import uuid4

import melder as md

crystallizer = md.Crystallizer()
configuration = md.CrystallizerConfigurationBuilder().with_defaults().activate()
crystallizer.activate(configuration)
profile_name = "readme-" + uuid4().hex
crystallizer.create_profile(profile_name, activate=True)
print("profile:", profile_name)

# Build the configured dynamic application and its bindings here, while recording.
checkpoint_id = crystallizer.create_checkpoint(description="pre-migration")
assert checkpoint_id in crystallizer.list_checkpoint_ids()  # in this process's ledger

crystallizer.describe_profile()               # what's recorded right now
crystallizer.describe_checkpoint(checkpoint_id)

flushed = crystallizer.flush_checkpoint(checkpoint_id)
assert checkpoint_id in flushed
assert checkpoint_id in crystallizer.list_cached_checkpoint_ids()  # bytes on disk
Expected outcome: a new profile name is printed, the checkpoint ID is recorded
immediately, and it is cached after the flush. create_checkpoint() alone does
not write the checkpoint to disk;
flush_checkpoint() stores it in the local cache and uses external storage when
configured. An application object's current fields are not serialized by either
step. External upload failures are lenient by default, so a returned ID is not
proof that a remote store received it. Before replaying into a live process,
retire original runtime claims that would collide with the restored structure.
To continue an existing profile, reload its cached history into the ledger first
(the bootstrap does this). A fresh empty ledger restarts checkpoint numbering;
flushing it into an already-full cache for that profile can immediately evict
the new checkpoint under the retention rule. Cache retention is bounded per
profile by max_persistence_crystals (100 by default).
Restore replays that world through public verbs only — the same bind,
conjure, link calls you would have written. Which means:
- Fresh identities always. ULIDs are minted new, never rehydrated.
- All-or-nothing. Any stage failure tears down everything in reverse order.
- An honest ledger. Anything unreplayable is a named shortfall, never a silent gap.
- Drift detection. Every load re-hashes your source against the sealed fingerprint and announces divergence before building anything.
A checkpoint you can't boot from is a diary. CrystallizerBootstrap is the
other half: one fluent chain that brings an entire world back on a cold
process.
This cold-process excerpt assumes your upload, download and list_ids
handlers are defined, profile_name is the name printed by the saving process,
and the saved application's classes remain importable.
The external manager is optional; omit that configuration for local-cache-only
recovery. Run the
cold-runtime lesson
to see flushing, teardown and reload as separate steps.
report = (
    md.CrystallizerBootstrap()
    .with_external_persistence_manager(          # optional: your own DB
        md.ExternalPersistenceManagerConfiguration()
        .with_upload_handler(upload)
        .with_download_handler(download)
        .with_list_handler(list_ids)
    )
    .with_profile(profile_name)
    .bootstrap()
)

report["activated"]              # crystallizer live
report["remote_reload"]          # what was pulled back from your store
report["restored_checkpoint_id"] # which world it booted
report["restore_report"]         # per-stage build counts + shortfalls
Expected outcome: activated is true. A process with no saved history starts
an empty world and reports restored_checkpoint_id as None; otherwise the
report identifies the restored checkpoint and any replay shortfalls.
That single chain does the whole cold start: activate → attach your storage → reload the local cache → pull from remote and re-flush it locally → verify the checkpoint chain → restore the newest world → hand you a report.
Storage is yours. Melder ships no database driver and no cloud SDK. You hand it four callables — store, fetch, list, delete — and it uses them. Your Postgres, your S3, your Redis, your rules. That's why the dependency list is empty.
A pod restarts, pulls its last checkpoint, and rebuilds the world structurally intact — no serialized objects, no pickle, no version-brittle blobs. The spell identity that comes back is the same content hash that went in.
Expert / agent-facing. Hot-swap a live implementation, with foresight and rollback.
This is where "hot reload" stops being a figure of speech. An agent can swap a live implementation for a new one on a running system — but first it has to answer the only question that matters: what does this break?
research = conduit.mutation_research     # the world's research record

# 1. WHAT IS THIS THING NOW? — declared lane, live state, stored custody
research.residency_view(spell_id)

# 2. WHAT DOES IT COST TO TOUCH IT? — transitive blast radius,
#    joined with which lanes and campaigns those spells live in
research.impact_view(spell_id=spell_id)

# 3. WHAT *WOULD* HAPPEN? — the read-only rehearsal
candidate = """
class ReportService:
    def run(self) -> str:
        return "v2 report"
"""
verdict = research.preview_candidate(candidate, against_spell_id=spell_id)
# → what it defines, what it imports, how it differs from the version it
#   would replace, and the radius that replacement would carry.
# NOTHING executes, binds, or records. It is a rehearsal, not a change.Foresight is half of it. The other half is the live swap — stage → notch → meld, on a running system, with the old version still sitting there:
# 1. STAGE — bind the edited ReportService (the candidate above, imported
#    from the module it now lives in) as an INACTIVE member of the existing
#    index. It is bound the way the index's first version was — bare, so
#    addressed by its name, ReportService, at the default binding — and a
#    version bound any other way is refused. It is parked and unresolvable:
#    nothing melds it, nothing sees it yet.
from reports_v2 import ReportService as EditedReportService

id_v1 = index.selected_spell_id     # the version serving now
id_v2 = conduit.bind_inactive(
    spell=EditedReportService,  # new code, the same name: a new spell_id
    spell_index=index,          # the index the current version lives in
    existence="unique",
)

# 2. NOTCH — promote v2 to ACTIVE. The outgoing version parks, the index
#    pointer repoints, and dependents are marked for lazy recompile.
conduit.notch_spell(spell_index=index, spell_id=id_v2)
assert index.selected_spell_id == id_v2

# 3. MELD — the very next resolution builds the NEW version, and the
#    address follows the notch: a meld by name gets it too.
service = conduit.meld(spell_id=id_v2)   # → the edited ReportService
assert conduit.meld("ReportService") is service
Every version of an index is bound the way its first version was — the
same kind of spellframe and the same address (spellframe or class name, and
binding name). That is why a notch never moves the address, and why
bind_inactive refuses a renamed class bound bare: it would be another
address. When versions will carry different class names, bind them all under
one spellframe category (spellframe="reports") from the first version on.
And because the old member is parked, not destroyed, rollback is the same verb pointed the other way:
conduit.notch_spell(spell_index=index, spell_id=id_v1) # instant revertThe parked version is still in the ecosystem. Notching does not dispose of anything — v1 remains a member of the index, holding its slot and its state. That's what makes the revert above instant, but it also means retirement is a deliberate act: the agent (or you) decides when a version leaves, and removes it explicitly. Nothing is swept up for you, and nothing disappears behind your back.
That's the whole loop: an agent reads the system, previews a change, stages it beside the live one, promotes it, and can put it back — while the process keeps running. Every world entry and promotion lands in a journal you can walk, in lanes with forward-only history and content-addressed identity (a unit's content hash is its identity, so the same code re-entering is a rediscovery, not a duplicate).
The point isn't that an agent can mutate your system. It's that it's shown the cost first, the change is staged rather than smashed in, and the previous version is one call away.
Everyone. Free-threading is the foundation, not a feature.
Every DI library in Python was designed when threads couldn't run simultaneously. "Thread-safe" meant "we put a mutex on it," because contention was theoretical.
Melder was written after that stopped being true.
- Lock-disciplined registries and scopes with a documented one-way lock order
- Concurrent resolution as a first-class path, not a footnote
- Real threads, real shared memory — no multiprocessing crutches
- Warns at import if it detects a GIL-enabled build
The reason Melder can be both fast and safe under real parallelism is that reads and writes don't share a road:
Readers — meld() |
Writers — structural change | |
|---|---|---|
| Path | Never enter the transaction plane | Admitted through the mediator |
| Protection | Validity gating: a stale graph is refused and recompiled | Moded scope claims (x / s / ix) |
| Contention | None with other readers | Only with work touching the same scopes |
| Cost | Resolution speed, uncompromised | Paid once, at the moment you change something |
Resolution — the thing you do thousands of times — carries no transaction overhead at all. Coordination is charged only to the thing you do rarely: changing the shape of the system.
That split is what makes the whole design hold together. Without free-threading there'd be no real parallelism to protect. Without the mediator, parallel structural change would be a race. You need both, and Melder was built assuming both from the first line.
Use the routes below to choose source-controlled architecture, runnable examples, hosted reference, or video walkthroughs. This README stays the runnable tour; long-form guides and API reference belong in the hosted documentation site.
| Where | What's there | |
|---|---|---|
| 🗺️ | Architecture and design | High-level pictures, runtime structure, utilization stories, and tradeoffs |
| 🖼️ | Engineering drawings | DI comparison, C4/C3/C2 views, use cases, lifecycle, coordination, recovery, and advanced flows |
| 🧪 | Runnable examples | Beginner-to-expert scripts organized by the same level ladder used in this README |
| ✅ | Example verification | Pytest harness and contract probes for the runnable curriculum |
| 📘 | Getting started | The guided introduction — start here after this page |
| 📚 | melder.readthedocs.io | Four learning levels, runnable examples, API reference, and full contents |
| Synaptic AI on YouTube | Walkthroughs, deep dives, and live builds |
GNU Affero General Public License v3.0 or later (AGPL-3.0-or-later) — see LICENSE.
The AGPL's network clause applies: if you run a modified version of Melder™ as a service that users interact with over a network, you must offer those users the corresponding source of your modified version.
Trademark. Melder™ is a trademark of Mark Thomas Geleta / Synaptic AI Systems. The AGPL grants rights in the software, not in the name — forks and redistributions must not use the Melder name or marks in a way that suggests endorsement by, or origin from, the trademark holder. See NOTICE.
Issues and design discussion welcome via GitHub issues.
Melder is under active architectural development — if you're planning something substantial, open an issue first so we can align on direction.
Built by Mark Geleta · Synaptic AI Systems
A better place for intelligence to live and work.