
Website · Docs · Blog · Docker Hub
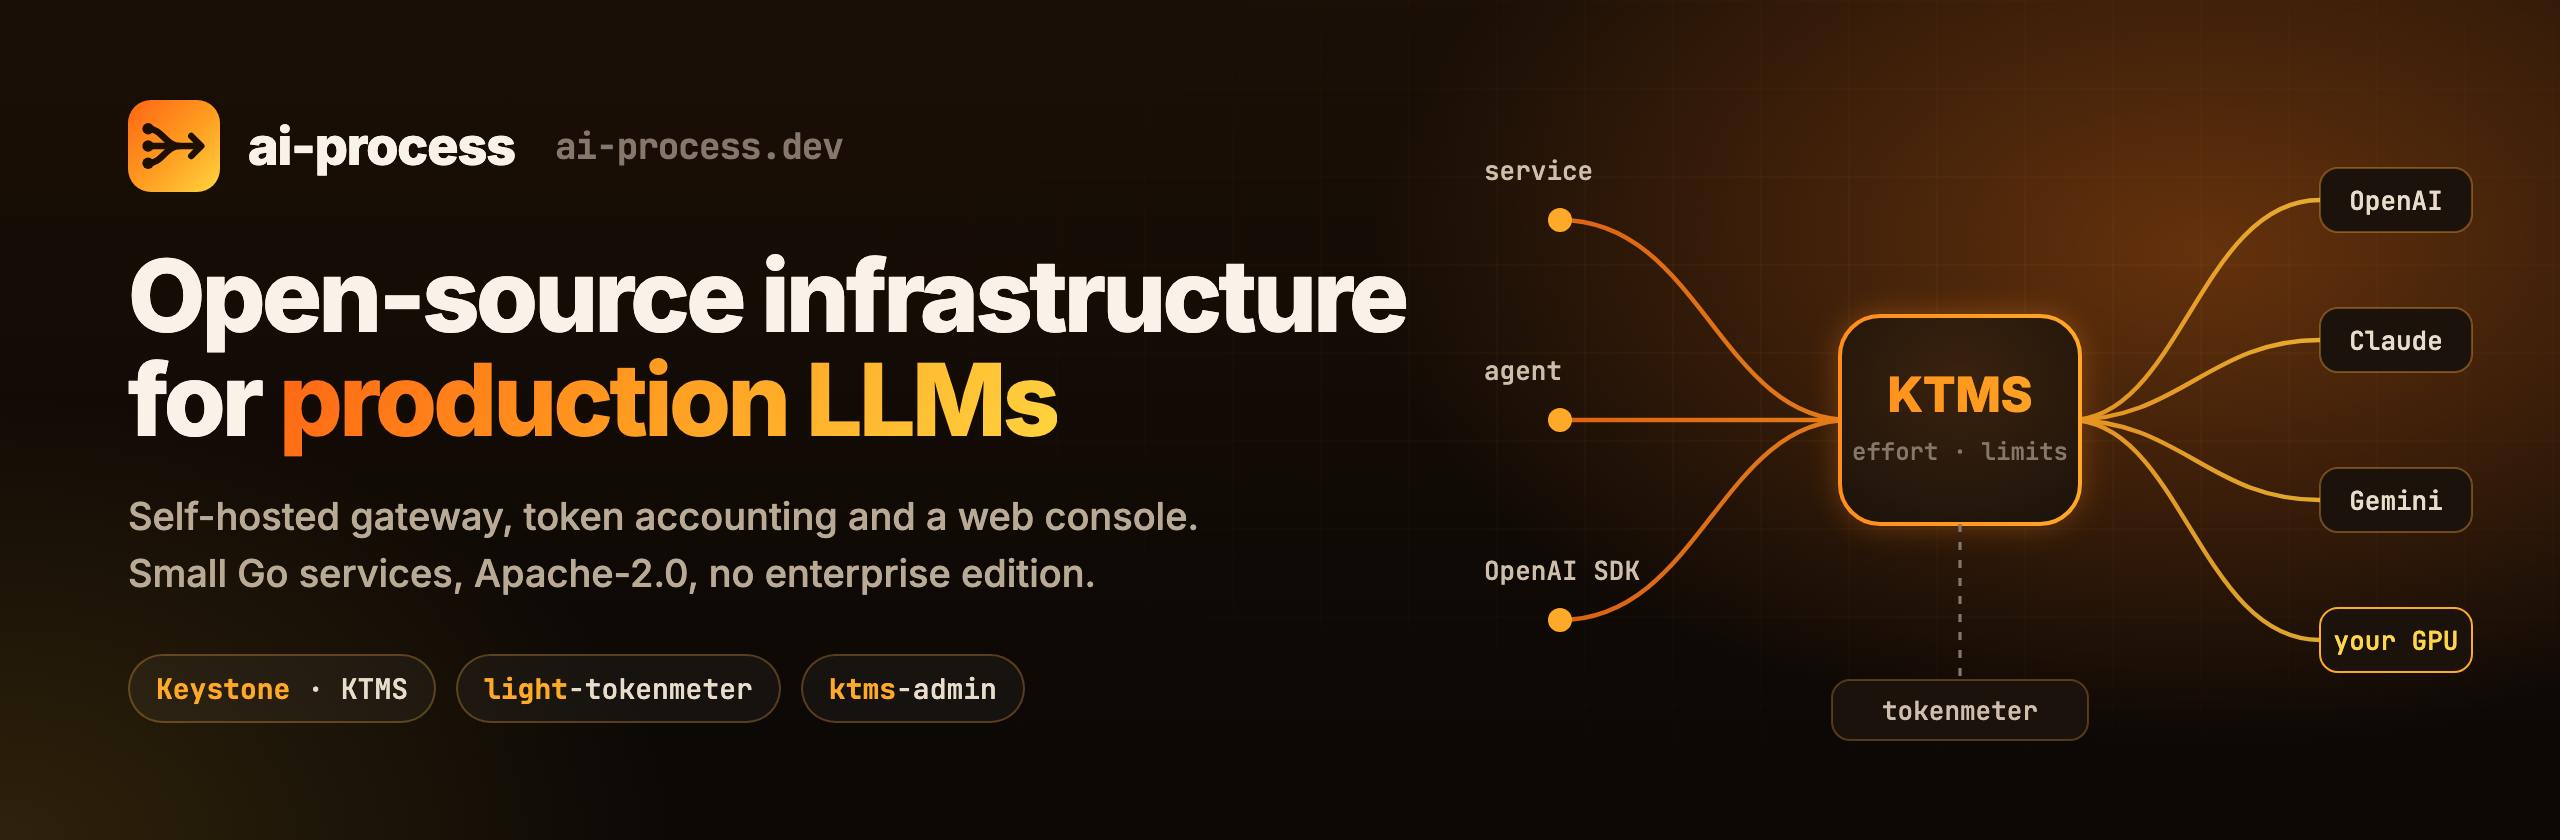
We build small, self-hosted services for teams that run LLMs in production: one gateway in front of every model, honest token accounting and a console to manage both. Everything is written in Go and released under Apache-2.0, with no enterprise edition.
| Project | What it does | |
|---|---|---|
| 🔀 | Keystone. The Model Switchboard. (KTMS) | LLM gateway: encrypted vendor keys, routing by effort with fallbacks, RPM and token budgets, batches, a local GPU node pool. gRPC and OpenAI-compatible HTTP. · docs |
| 📊 | light-tokenmeter | Usage meter: one event per model call, daily summaries by project, user, model or action, and who is greedy vs worthy. · docs |
| 🖥️ | ktms-admin | Web console for both: models, rules, keys, a prompt playground and the spend dashboard. · docs |
git clone https://github.com/ai-process/ktms.git && cd ktms
OPENAI_API_KEY=sk-... docker compose up -d --build

curl -s http://localhost:8080/v1/chat/completions \
  -H "Authorization: Bearer ktms_dev_default_key" \
  -H "Content-Type: application/json" \
  -d '{"model":"auto","messages":[{"role":"user","content":"Say hi"}]}'
Point any OpenAI SDK at http://localhost:8080/v1 and KTMS picks the model, falls back when a vendor fails and enforces your limits. See the architecture guide to run the whole stack.