





Lead AI Product Manager & Builder — Agentic AI · leading the 0→1 Agentic AI Digital Advisor at Vanguard · ex-T-Mobile, eBay · Stanford GSB
10+ years launching 0→1 products and scaling platforms 1→100 across fintech, SaaS and enterprise platforms, and marketplaces: $9B+ in revenue platforms, 29M+ MAU, $300M+ in cost savings. On the side I build the eval and trust tooling I wish every AI team had, and I publish the failures along with the passes.
vishal_walkthrough_titled.mp4
What ties it together: AI output is only worth shipping when it can be checked against a source of truth, whether that's an IRS rule, a tool's own schema, or a platform's API contract.
⏱️ Got 2 minutes? Start here:
- A real report from a real user: an outside maintainer opened an issue and a bot graded their MCP server. No install needed.
- A red team that broke my own checker: all 22 in-scope attacks got through, and I published it as-is.
- Try a checker yourself: an agent-to-agent handoff, decided ACT, ESCALATE or BLOCK, in your browser.
- A 155K★ project built its fix on my PR: Langflow's maintainer adapted my fix for MCP tool arguments and credited me as co-author.
None of these maintainers work with me.
"Thank you for the exact tools/list results and for explaining the effect on clients that use annotations for approval." (
codebase-memory-mcpmaintainer)
"Thanks for shipping this and keeping the regression case." (an outside tester whose agent found the bug)
- Fixes merged upstream, all reviewed and merged by the projects' own maintainers:
langflow(155K★): MCP tool arguments named after component methods, such asindex, were sent as the method instead of the configured value. The maintainer built the fix on my PR and credits me as co-author.mcp-for-blender(30K★): optional tool arguments now accept an explicit null, re-applied by the maintainer on a refactor with me as commit author.davinci-resolve-mcp(3.4K★): 16 optional arguments on 9 tools rejected an explicit null, now 0. Shipped in v4.8.29 with a credit in the release notes.jupyter-mcp-server(1.3K★), 2 fixes:connect_to_jupyternow checks the server before reporting success, andtools/listno longer reads the server mode before it is set.- 13 more:
ha-mcp(5.0K★) ·dbhub(3.6K★) ·google_workspace_mcp(3.3K★) ·shadcn-ui-mcp-server(3K★) ·llm-wiki-compiler(2.2K★) ·stealth-browser-mcp(2.2K★) ·telegram-mcp(1.8K★) ·Qiskit/mcp-servers(IBM) ·jadx-mcp-server(794★) ·MCP-PostgreSQL-Ops·open-meteo-mcp·devglobe·osm-mcp-server
- Both of my fixes to
excel-mcp-server(4.2K★) were reimplemented in its v1.0.0 rewrite, credited in the changelog - Maintainers shipped fixes after my findings:
codebase-memory-mcp(46.3K★) relabeled all 12 mislabeled read-only tools; plusmcp-server-chart(4.4K★) andagent-inspect - Two contributors on the official MCP spec discussion reported two real bugs and a spec gap in my tools; all three are fixed
- A public leaderboard grading 24 MCP servers, 3 added by an outside maintainer through the no-install scan, and real skill runs you can read without installing anything
🗺️ Where my work sits in the AI stack: what I shipped at work vs. built in the open, layer by layer
| Layer | Shipped at work | Built in the open |
|---|---|---|
| Apps & human-in-the-loop | 🏦 Vanguard Digital Advisor experience · 🏢 T-Mobile agentic support platform | 🏦 Contribution room calculator · 🏦 Human review queue · 🛒 Listing checker demo |
| Agents & orchestration | 🏦 Agentic AI Digital Advisor (0→1) · 🏢 Autonomous enterprise agent platform | GuardedSession: ACT, ESCALATE or BLOCK on each live tool call · 🏢 agent-handoff-check: authority can only narrow across handoffs |
| Tools & APIs (MCP) | 🛒 eBay API standardization across hundreds of teams | mcp-doctor, mcp-fuzz, mcp-reality-check · 🏦 check_answer and contribution_room MCP tools · 🛒 check_listing MCP tool |
| Evals & quality | 🏦 Model evals for correctness, groundedness, safety, latency · 🏢 IntentCX evaluation framework | 🏦 Blind, pre-registered evals · 🛒 Failed blind run, fresh pass, then broken by a red team · 🏢 RAG prototype on blind tickets: accuracy fell from 60% to 38% · ⚛️ Quantum circuit grader: right on all 90 real answers, yet 4 red teams got 27 wrong circuits passed (write-up) · /eval-plan |
| Guardrails, governance & risk | 🏦 FINRA/SEC-compliant responsible AI design · 🏢 Governance aligned to NIST AI RMF | 🏦 Model risk pack (SR 26-2 + NIST AI 600-1) · 🏦 Prompt-injection red team, before and after the fix · mcp-trust-check release gate · 🏢 Red-teamed handoff checks |
| Cost & pricing | 🏢 Accuracy, cost and latency tuned per interaction type | 🏢 Which model, and how to price it |
| Product decisions | 0→1 strategy, launch gates, adoption and containment metrics | PRD: Agent Outcome Trust Score · /build-or-not · Agent Readiness Scorecard · What I decided not to build · Who owns trust for agent tools |
🏦 Fintech
- 🛡️
retirement-answer-check: checks an AI's draft answer to a retirement-account question before a customer sees it, and decides SEND or REVIEW with an IRS or FINRA source for every flag.
Pattern rules alone let 5 of 15 blind wrong facts through; adding a fact-checking judge brought that to 0 of 25. Also: contribution room calculator · model risk pack
🛒 Marketplaces
- 🏷️
listing-claim-check: checks an AI-written listing against the seller's own item specifics and decides PUBLISH or REVIEW. Try it →
v0.1 failed its blind run and v0.2 passed a fresh one, then a red team got all 22 attacks through. Published as-is. - 🧩 eBay case study: the platform behind $300M+ in savings, and why clear contracts matter for agents.
🏢 SaaS & enterprise platforms
- 🔗
agent-handoff-check: checks every agent-to-agent handoff against what the customer authorized and decides ACT, ESCALATE or BLOCK. Try it →
A red team got 3 unauthorized calls through; after one design change, a fresh blind run let 0 of 18 through and blocked 0 of 14 legitimate calls. - 📡 T-Mobile case study: four architecture decisions behind the agentic platform (25M users, 60% containment) and what I'd do differently.
- 📊 Which model, and how to price it: model cost is under 5% of the value delivered, so the real constraint is draft quality.
🧰 Trust tooling for the tools AI agents call (MCP)
- 🩺
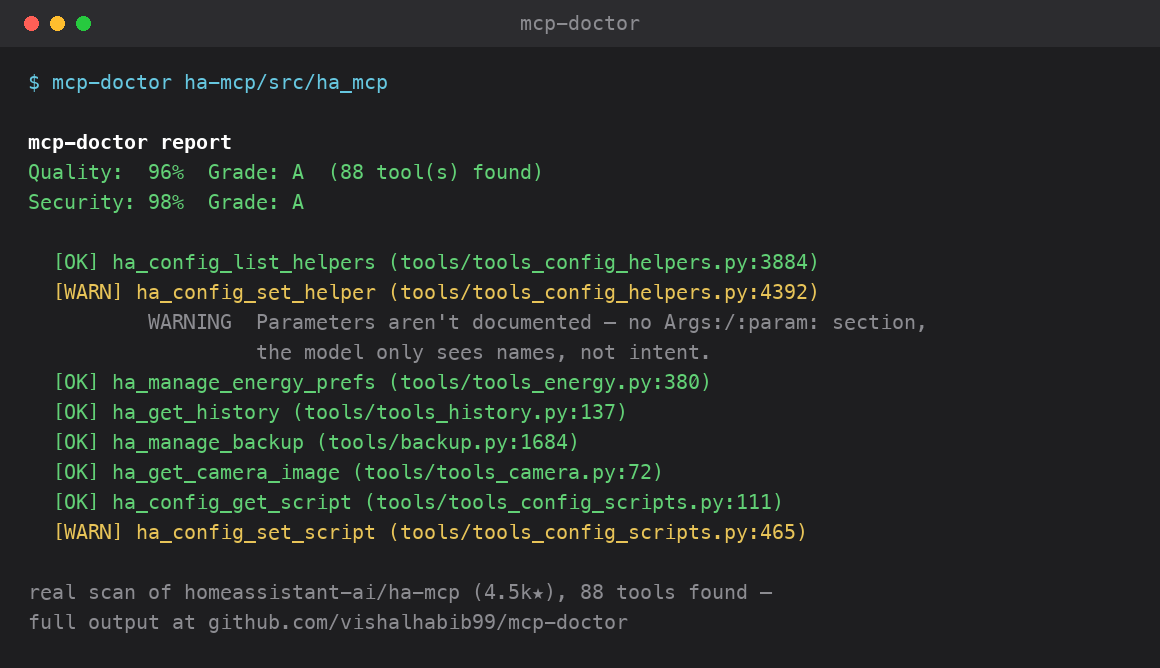
mcp-doctor: for MCP server maintainers who need to know whether an agent can actually use their tools. Open an issue with your repo URL and a bot replies with a graded report, or add the GitHub Action for one-click fixes on every PR. Scan your server →
Finds 15,755 of 15,977 tools across 805 real servers, with every miss published. Scanning real servers surfaced 102 bugs in mcp-doctor itself, all fixed (postmortem). What the first users taught me →
A bet I made before knowing the answer: at least 10 outside scan requests by Oct 27, or I stop promoting mcp-doctor. 3 so far (as of Oct 10), all from one maintainer I invited. The result gets posted here either way. - 🧪
mcp-fuzzchecks that a live server fails cleanly · 🩻mcp-reality-checkcatches "successful" responses that aren't · 🛡️mcp-trust-checkruns all three as one GitHub Action that decides SHIP, FIX-FIRST or BLOCK.
🧭 For AI product managers
- 🧭
ai-pm-skills: Claude Code skills (/build-or-not,/eval-plan,/agent-trust-review), each tested against gates set before the first run. See real runs → - 📋
agentic-product-playbook: 7 ways AI agents fail in production, plus templates. 3-minute Agent Readiness Scorecard → - 📄
ai-pm-portfolio: PRDs, prototypes and honestly reported evals, failures included.
- I scanned 3,923 MCP servers. 1 in 4 tools leaves the model guessing.: a census of 3,923 public MCP servers (20+ stars), 147,646 tools, scripts (dev.to)
- 5 ways AI agents fail, and the checks I built in public: accuracy, safety, security, quality and evals, one number each (LinkedIn)
- Building T-Mobile's First Enterprise Agentic AI Platform: 25M Users, 75% Adoption, and What I'd Do Differently (LinkedIn)
More writing
- My grader got every real answer right. Four red teams still broke it. (dev.to)
- "0 of 18 got through" isn't a launch. Here's the number that is. (dev.to)
- My prompt-injection fix caught 0 of 20 attacks. The part I almost didn't build caught all of them. (dev.to)
- I set the pass bar before testing my Claude Code skills. The first run failed. (dev.to)
- My tools were rigorous. They were also hard to try. (LinkedIn)
- I built three tools to audit MCP servers. Each one found a bug in itself first. (dev.to)
Vanguard · T-Mobile · eBay · earlier roles
- 🏦 Fintech: Vanguard. Product strategy for Digital Advisor and Personal Advisor ($6B+ LOB, 4M+ MAU) at the world's second-largest asset manager (~$12T AUM). Architecting the Agentic AI Digital Advisor from 0→1: LLM orchestration, agent workflows, model evals and FINRA/SEC-compliant responsible AI. Also launched T-Mobile Money and, earlier, digital lending modernization at Axis Bank.
- 🏢 SaaS & enterprise platforms: T-Mobile. Product lead for T-Life, the flagship app ($3B+ LOB, 25M+ MAU); managed 3 PMs and a 40+ person org. Launched one of the first autonomous enterprise Agentic AI platforms in US telecom: 75% adoption, 60% containment, 80% CSAT, 30% fewer support calls. Built the IntentCX AI governance and eval framework (NIST AI RMF), adopted by 3 more teams. AI personalization: +27% engagement, +15% conversion.
- 🛒 Marketplaces: eBay. Drove $300M+ in savings and +35% adoption through platform modernization and API standardization across hundreds of teams; 40% faster deploys, 99.9% availability on seller APIs.
- 🩺 Earlier, healthcare: Premera Blue Cross. Billing and payment redesign that cut task completion time 25%.
Recognition
- Patent filed: sole inventor on a U.S. provisional patent application (No. 63/980,243, May 2026) for agentic AI orchestration and governance.
- Top Product Leader, T-Mobile (2025), for building and launching the enterprise agentic AI platform.
- Keynote speaker, T-Mobile Technology Innovation Summit (2025): AI strategy keynote to 1,200+ attendees.
Education & certifications
- Stanford Graduate School of Business: Executive Program, Harnessing AI for Breakthrough Innovation and Strategic Impact (2026)
- MBA, Business Strategy and Marketing, Indiana University of Pennsylvania · MS, Information Technology Management, Campbellsville University
- Certifications: PMP · SAFe POPM · AWS Solutions Architect Associate · CSPO · PMI-PBA · Google AI Essentials
What this portfolio doesn't cover
- Semantic hallucination ("is this answer true" in general): it needs an LLM judge, which would break the deterministic, no-API-cost design of the MCP tools.
retirement-answer-checkuses a judge only for narrow fact checks against IRS and FINRA sources. - Live agent red-teaming:
mcp-doctor's security score audits a tool's code and description for injection risk, not whether a live agent can be manipulated at runtime.